This is the plainest of the AI checks and, perhaps because of that, one of the higher-scoring: it does not ask what the page says, only how it is built. Sentence length, paragraph length, vocabulary complexity, rhythm. Most sites write reasonably plainly without trying, which is why the median sits comfortably above the middle of the dataset — and why the pages that fail here tend to fail badly rather than marginally.
Here is where that sits. The median SeoMods score is 75/100, which ranks it 7 of the 25 tools with a published benchmark by median. The ranking runs over the 25 tools on the main benchmark page; 1st is the highest median. The middle half of results falls between 58 and 83 — a band 25 points wide. That is wide: in this sample sites’ scores diverge markedly on this measure.
How the scores are distributed
An average on its own misleads. The chart below splits all 3,414 scans into five score bands, totalling 100%. Most results sit in the middle bands, which means sites differ here by degree rather than by whether they bothered at all.
- 0–19
- 20–39
- 40–59
- 60–79
- 80–100
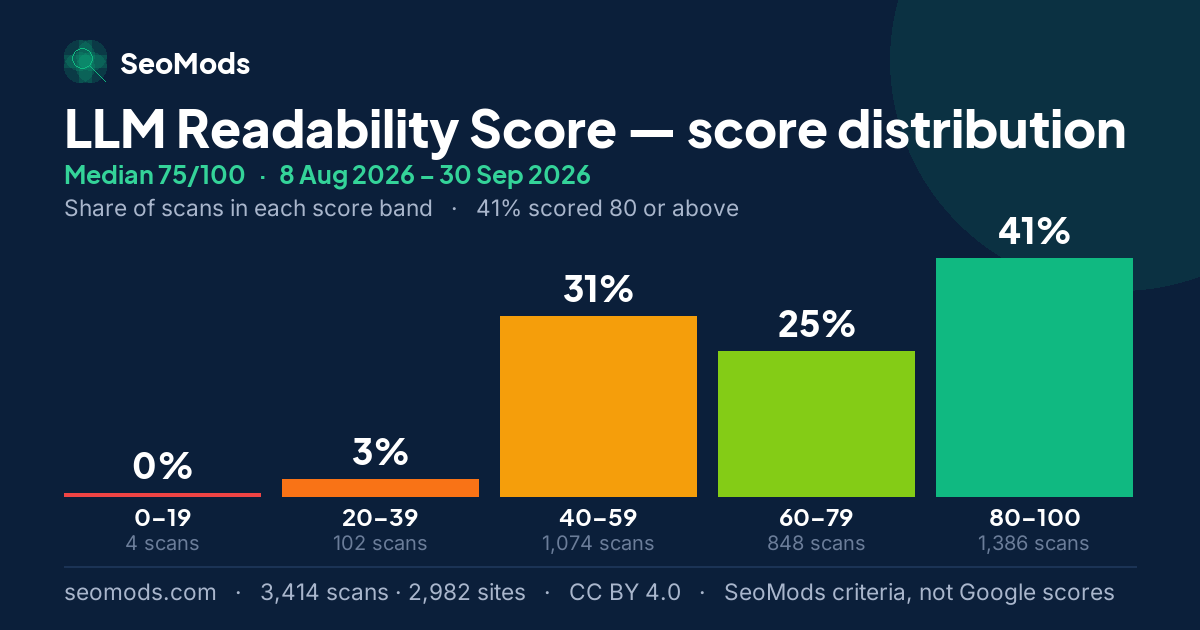
| Score band | LLM Readability |
|---|---|
| 0–19 | 0% · 4 |
| 20–39 | 3% · 102 |
| 40–59 | 31% · 1,074 |
| 60–79 | 25% · 848 |
| 80–100 | 41% · 1,386 |
| Total runs | 3,414 |
The grade mix
The same data as letters: A+ 95–100, A 85–94, B 75–84, C 65–74, D 50–64 and F below 50.
Where does my score sit?
A high score is not a compliment about your prose and a low one is not an insult. This measures machine-parseability, and the two occasionally diverge: dense, subordinate-clause-heavy writing can be a pleasure to read and genuinely hard to chunk. If you score badly and your readers do not complain, the fix is structural — break the long sentences, keep the voice.
| Tool | P10 | P25 | Median | P75 | P90 | Mean | Lowest | Highest |
|---|---|---|---|---|---|---|---|---|
| LLM Readability | 47 | 58 | 75 | 83 | 94 | 70.8 | 6 | 100 |
A score from the LLM Readability Score can be read against the five values below. All of them are calculated from the scans in this benchmark: they place a SeoMods score within this sample, not in Google’s results.
| Percentile | Score | What it means for a score |
|---|---|---|
| P10 | 47 | About one scan in ten scored 47 or lower. Below it, a page is in the lowest tenth of this sample. |
| P25 | 58 | The edge of the bottom quarter. A score under 58 is below about three quarters of the scans. |
| Median | 75 | The middle of the sample: half the scans scored lower, half higher. A score of 75 is the typical result here. |
| P75 | 83 | Where the top quarter begins. A score of 83 or more is at or above about three quarters of the scans. |
| P90 | 94 | Where the top tenth begins. A score of 94 or more is among the highest 10% of scans in this sample. |
Percentiles describe the sites SeoMods scanned, not the whole web, and they apply to this tool only: the same number on another tool sits somewhere else.
The SeoMods checks most often unmet
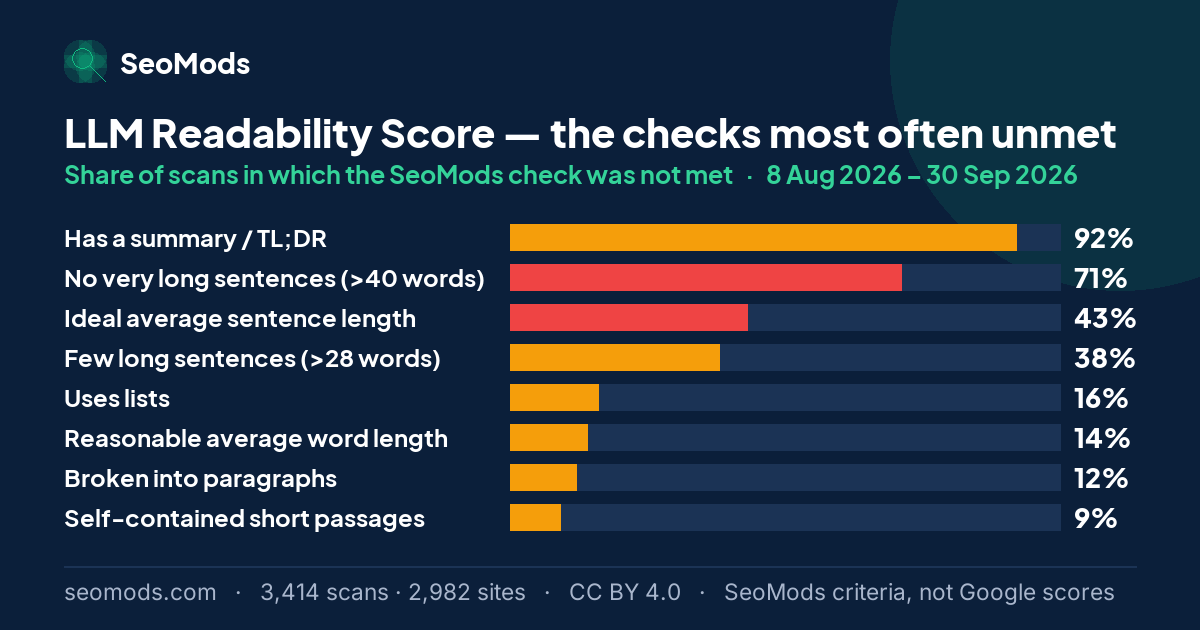
The failures cluster around length: sentences that run past the point where a parser loses track of the subject, and paragraphs that never break. There is a secondary group about variety — writing where every sentence is the same length reads as machine-generated to a machine, which is a pleasing irony but also a real signal.
| Check | Not met (share of scans) | Weight |
|---|---|---|
| Has a summary / TL;DR | 92% | Partial |
| No very long sentences (>40 words) | 71% | Hard fail |
| Ideal average sentence length | 43% | Hard fail |
| Few long sentences (>28 words) | 38% | Partial |
| Uses lists | 16% | Partial |
| Reasonable average word length | 14% | Partial |
| Broken into paragraphs | 12% | Partial |
| Self-contained short passages | 9% | Partial |
| Healthy lexical variety | 8% | Partial |
| Varied sentence rhythm | 7% | Partial |
| Low share of long/complex words | 3% | Partial |
The rate is the share of scans in which a SeoMods check was not met. It is SeoMods’ criterion, not Google’s assessment of these pages. “Hard fail” means the check’s full weight is deducted from the SeoMods score; “partial” means part of it.
The weakest areas
This tool groups its checks into categories. The chart below shows how often each category was the lowest-scoring one in a scan — which area is most often the weak link. It is not the average score in that category; it is how often it came last.
“Rhythm & Directness” was the weakest area in 50% of scans.
What to fix first
Split the longest sentences on the page and nothing else, then re-run. Sentence length dominates this score, and halving three or four of the worst offenders usually moves it more than any amount of vocabulary simplification. Long sentences are also where ambiguity hides for human readers.
A typical scan passes 7.9 of 11 checks and leaves 3.1 open items behind. In this sample what brings a SeoMods score down is mostly not one large omission but accumulated small ones.
Run the LLM Readability Score on your own page
Month by month
This page adds every published month together. Underneath it, each month is frozen as an edition of its own whose figures are never edited again — which is the only reason two months can be set side by side at all. Below is the LLM Readability Score across the 2 published editions, with the combined figure in the last row of the table.
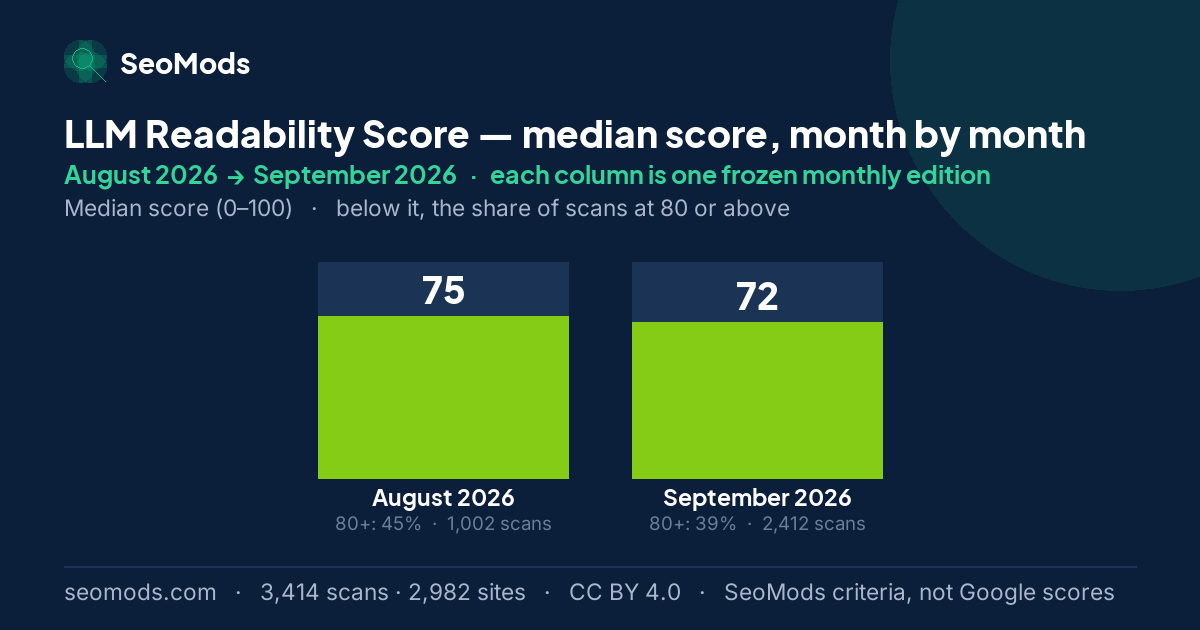
Between August 2026 and September 2026 the median went from 75 to 72, and the share of scans at 80 or above went from 45% to 39%. The two months do not measure the same sites — the September 2026 sample has about 3 times as many sites — so read the gap as a change in the cross-section measured, not as the same sites getting better or worse.
| Edition | Median | vs. previous | Scored 80+ | Issues/run | Runs |
|---|---|---|---|---|---|
| August 2026 | 75 | baseline | 45% | 2.9 | 1,002 |
| September 2026 | 72 | −3 pts | 39% | 3.2 | 2,412 |
| All published months, combined | 75 | — | 41% | 3.1 | 3,414 |
Reading a monthly difference. Each month is a separate sample, and its size changes from month to month. A change in sample size can move a median and a distribution by itself, so a monthly difference should not be mistaken for a change in scores: it does not show that sites improved or got worse.
Which checks moved
Each check’s rate in the first edition that measured it, beside its rate in the latest. Moves under two points are marked as no change: these are independent monthly samples of a shifting set of sites, and a difference that small is not evidence that anything on the web changed.
| Check | Not met in August 2026 | Not met in September 2026 | Change |
|---|---|---|---|
| Ideal average sentence length Hard fail | 35% · August 2026 | 46% · September 2026 | +11 pp |
| Reasonable average word length | 9% · August 2026 | 17% · September 2026 | +8 pp |
| Few long sentences (>28 words) | 33% · August 2026 | 40% · September 2026 | +7 pp |
| Uses lists | 19% · August 2026 | 14% · September 2026 | −5 pp |
| Has a summary / TL;DR | 94% · August 2026 | 91% · September 2026 | −3 pp |
| Broken into paragraphs | 10% · August 2026 | 13% · September 2026 | +3 pp |
| Self-contained short passages | 7% · August 2026 | 10% · September 2026 | +3 pp |
| Low share of long/complex words | 1% · August 2026 | 4% · September 2026 | +3 pp |
| Varied sentence rhythm | 6% · August 2026 | 8% · September 2026 | no change |
| No very long sentences (>40 words) Hard fail | 70% · August 2026 | 71% · September 2026 | no change |
| Healthy lexical variety | 9% · August 2026 | 8% · September 2026 | no change |
What this score does not measure
- It is not a direct measurement of the signals every AI system uses. Which system uses which signal, and how, is not public; the score measures the checks SeoMods chose.
- It does not measure whether a page is actually cited in AI answers. It measures readiness on the page, not what any assistant returned.
- It is not a Google ranking. A high score does not guarantee a better position, and a low one does not mean Google has penalised the page.
About this benchmark. This benchmark is calculated from data on the sites SeoMods has scanned. The results do not necessarily represent all websites, or a random selection of them. The scores express SeoMods’ own measurement and scoring criteria; they are not ranking, quality, E-E-A-T or AI visibility scores issued by Google. Sample, anonymization and licence: the full methodology.
Frequently asked questions
Does simpler writing actually help with AI search?
It helps with the mechanical part of it. A model that has to segment a page into passages does that more reliably when the boundaries are clear, and a clean segment is more likely to be quoted accurately. It does nothing for whether your argument is right or your information is worth having — plain writing makes good content usable, it does not make weak content good.
What sentence length should I aim for?
Around twenty words on average, with genuine variation around it. The average matters less than the tail: one forty-word sentence does more damage than a slightly high mean, because that is where a parser loses the subject. Varying deliberately between short and medium reads better to a person too.
Is this the same as a Flesch reading-ease score?
Related but not the same. Flesch is calibrated to human reading difficulty using syllables and sentence length. This adds the things that matter to a machine specifically: whether passages are self-contained, whether the page is chunked into retrievable units, and whether structure marks where one idea ends and the next begins.
What is a good score on the LLM Readability Score?
In this dataset the median SeoMods score is 75/100, so scoring 75 sits exactly in the middle of the sample. 83 is the start of the upper quartile and 94 or above is the top 10%; below 58 is the bottom quarter. Those thresholds are specific to this tool — the 25 tools with a published benchmark have very different medians, so 70 here and 70 elsewhere do not mean the same thing. They place a page among the sites SeoMods scanned; they say nothing about Google rankings.
Is the score from the LLM Readability Score issued by Google?
No. It is a benchmark score calculated against the check list SeoMods defined for this tool. A SeoMods check going unmet does not mean Google has penalised the page or ranked it lower.
Which SeoMods check goes unmet most often on the LLM Readability Score?
“Has a summary / TL;DR”, which was not met in 92% of scans. The largest losses on the SeoMods score, though, come from the checks scored as hard fails — this tool has 2, the most common being “No very long sentences (>40 words)” at 71%.
Questions that govern the whole series — how the sample is collected, how sites are anonymized, how often the figures are refreshed — are answered in the methodology on the hub.
Using this data
The figures, tables and charts on this page are free to reuse under CC BY 4.0; the only condition is a link back to this page. Suggested citation: SeoMods — LLM Readability Score benchmarks, 2 October 2026, https://seomods.com/seo-score-benchmarks/llm-readability-score. If you need to cite by date, use the September 2026 edition instead: this page changes at every refresh and that one never does.